
Dumitru Erhan
I’m Dumi, born in Moldova, now living in San Francisco. I work at Google DeepMind, where I lead research on generative video foundation models and world models. Some things I enjoy are cycling, cooking, espresso, techy gadgets, cats, and of course neural nets.

Now
At Google DeepMind, I am a Senior Research Director and co-lead of Gemini Omni. I was also a lead of Veo and Phenaki, focusing on generative video foundation models and world models that learn how the physical world behaves.
Google Brain
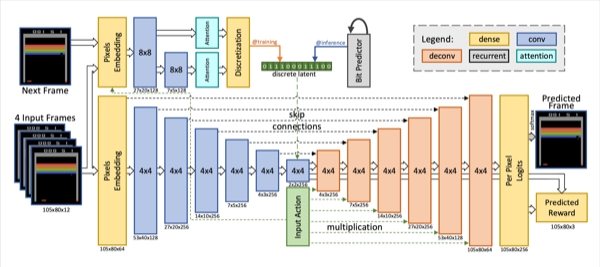
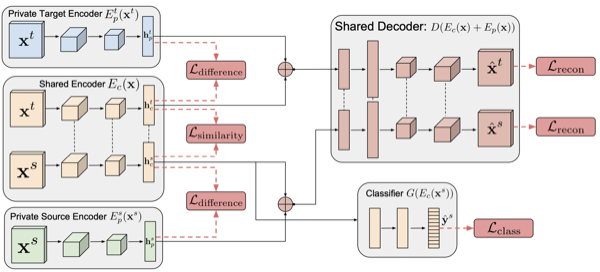
While in Google Brain, I focused on video prediction and model-based reinforcement learning—training agents entirely inside learned world models (SimPLe, SV2P, FitVid). We also explored simulation-to-reality domain adaptation with Domain Separation Networks and PixelDA.
Foundations
Earlier at Google, I worked on foundational vision architectures and core behaviors—including Inception (GoogLeNet), SSD, adversarial examples, and Show and Tell. I also spent a few years on the early Google Photos team, building visual search models ahead of its 2015 launch.
Previously
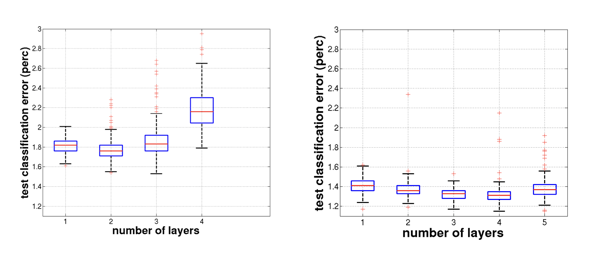
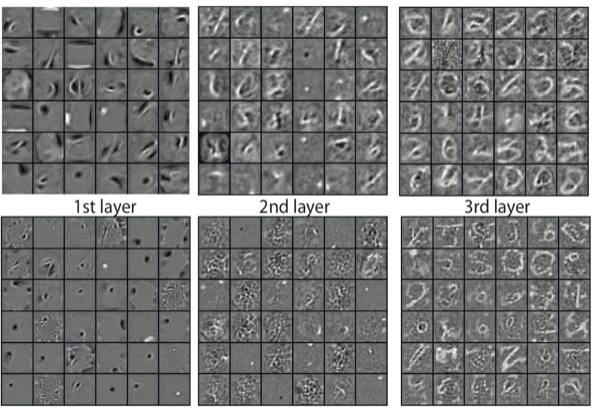
I did my PhD at the University of Montreal (now Mila) on deep learning with Yoshua Bengio, studying deep representations (feature visualization, unsupervised pre-training). Before Google, I spent 2011–2012 at Yahoo Labs working on search ranking.
Selected Papers
The through-line: understanding representation learning → interpreting deep networks → scaling visual recognition/detection → connecting vision and language → discovering failure modes → making perception fast → learning under imperfect supervision/domain shift → predicting video/world dynamics → generative video → unified multimodal generation.
A recurring theme has been taking research all the way from new ideas and benchmarks to systems and products used at scale.
-
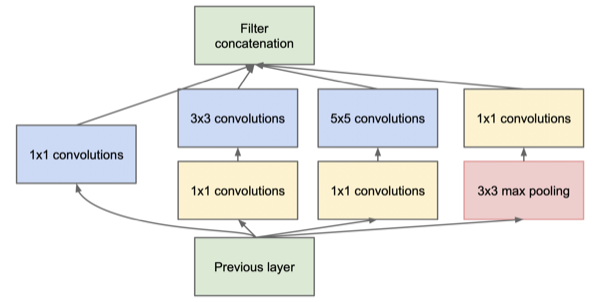
Going Deeper with Convolutions (CVPR 2015)
Introduced the 22-layer Inception architecture; won ImageNet 2014 and the CVPR 2025 Test of Time Award (Longuet-Higgins Prize). -
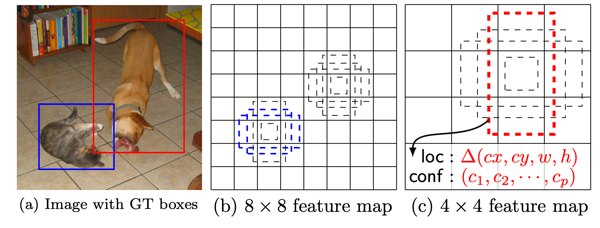
SSD: Single Shot MultiBox Detector (ECCV 2016)
Eliminated region proposals to enable fast, single-stage real-time object detection; won the ECCV 2026 Test of Time Award. -
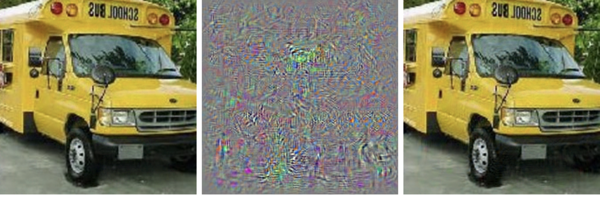
Intriguing Properties of Neural Networks (ICLR 2014)
Discovered adversarial examples and unlocalized representations, helping establish adversarial robustness as a major area of study. -
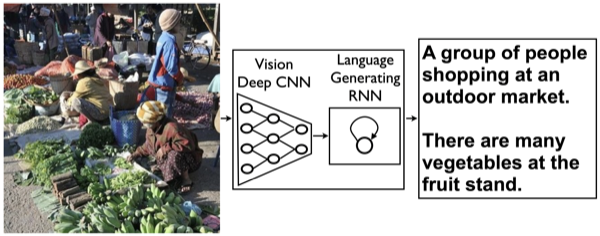
Show and Tell: A Neural Image Caption Generator (CVPR 2015)
First end-to-end deep neural network translating visual scenes to natural language descriptions; tied for 1st place in the COCO 2015 challenge. -
Phenaki: Variable Length Video Generation from Open Domain Text (ICLR 2023)
Pioneered causal spatio-temporal video tokens and masked transformers to synthesize variable-length video stories from sequential text prompts. -
Model-Based Reinforcement Learning for Atari (SimPLe) (ICLR 2020)
Showed that agents can learn complex behaviors with high sample efficiency by training entirely inside learned video prediction world models. -
Domain Separation Networks (NeurIPS 2016) & PixelDA (CVPR 2017)
Disentangled shared vs. domain-private representations, and introduced generative pixel-level domain adaptation from simulation to reality. -
Why Does Unsupervised Pre-training Help Deep Learning? (JMLR 2010)
Landmark empirical study demonstrating that pre-training acts as an unusual regularizer, conditioning optimization toward superior basins of attraction. -
Visualizing Higher-Layer Features of a Deep Network (2009)
Introduced activation maximization for visualizing receptive-field preferences, an early approach to neural network feature visualization.
A complete list of 100+ publications can be found on Google Scholar and ResearchGate.
Awards & Competitions
- ECCV 2026 Test of Time Award (announcement): for SSD: Single Shot MultiBox Detector
- CVPR 2025 Test of Time Award (Longuet-Higgins Prize): for Going Deeper with Convolutions
- ICLR 2024 Test of Time Runner-Up (announcement): for Intriguing Properties of Neural Networks
- MS COCO Captioning Challenge 2015: Tied for 1st place with Show and Tell (results)
- ImageNet (ILSVRC) 2014: Won 1st place in both classification and object detection with GoogLeNet (results)
Products & Press
- Gemini Omni (2026): Gemini app, Flow, YouTube Shorts · Google Launch · TechCrunch
- Veo 3 (2025): Gemini app, Flow, YouTube Shorts (230M+ videos generated) · Google Launch · TechCrunch · The Verge
- Phenaki (2022): foundational video model powering Google’s generative video roadmap · Google Research · Ars Technica
- Google Photos (2015): visual search in Photos (1.5B+ monthly users) · Google Announcement · The Verge
- Image Captioning (2014): automated descriptions in Google Photos & Cloud Vision · Google Research · The New York Times
- GoogLeNet / Inception (2014): visual search in Google Images, Photos & YouTube · Google Research · MIT Technology Review
Talks & Videos
SOTA Generative Media Panel

How a Moonshot Led to Google DeepMind's Veo 3
Visual Self-supervised Learning and World Models
RE•WORK
Video Interview
Interview with Dumitru Erhan
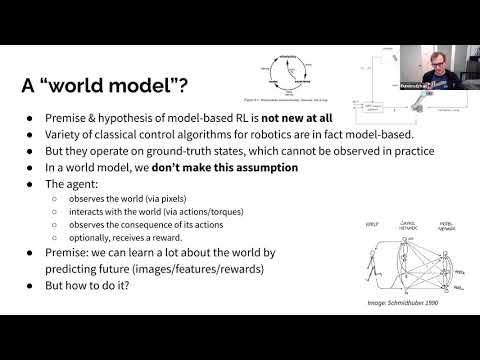
Applied Mathematics Colloquium
Mentorship
I’ve had the privilege of mentoring fantastic researchers over the years:
- Sara Hooker · CEO, Adaption Labs
- Wei Liu · AI Researcher, Meta
- Scott Reed · AI Researcher
- Ilya Kostrikov · OpenAI
- Mengye Ren · Asst. Professor, NYU
- Mohammad Babaeizadeh · Google DeepMind
- Ruben Villegas · Google DeepMind
- Homanga Bharadhwaj · Asst. Professor, Johns Hopkins
- Thanard Kurutach · Reflection AI
- Will Harvey · Netflix
- Julius Kunze · ML Researcher
- Marcin Moczulski · Oxford